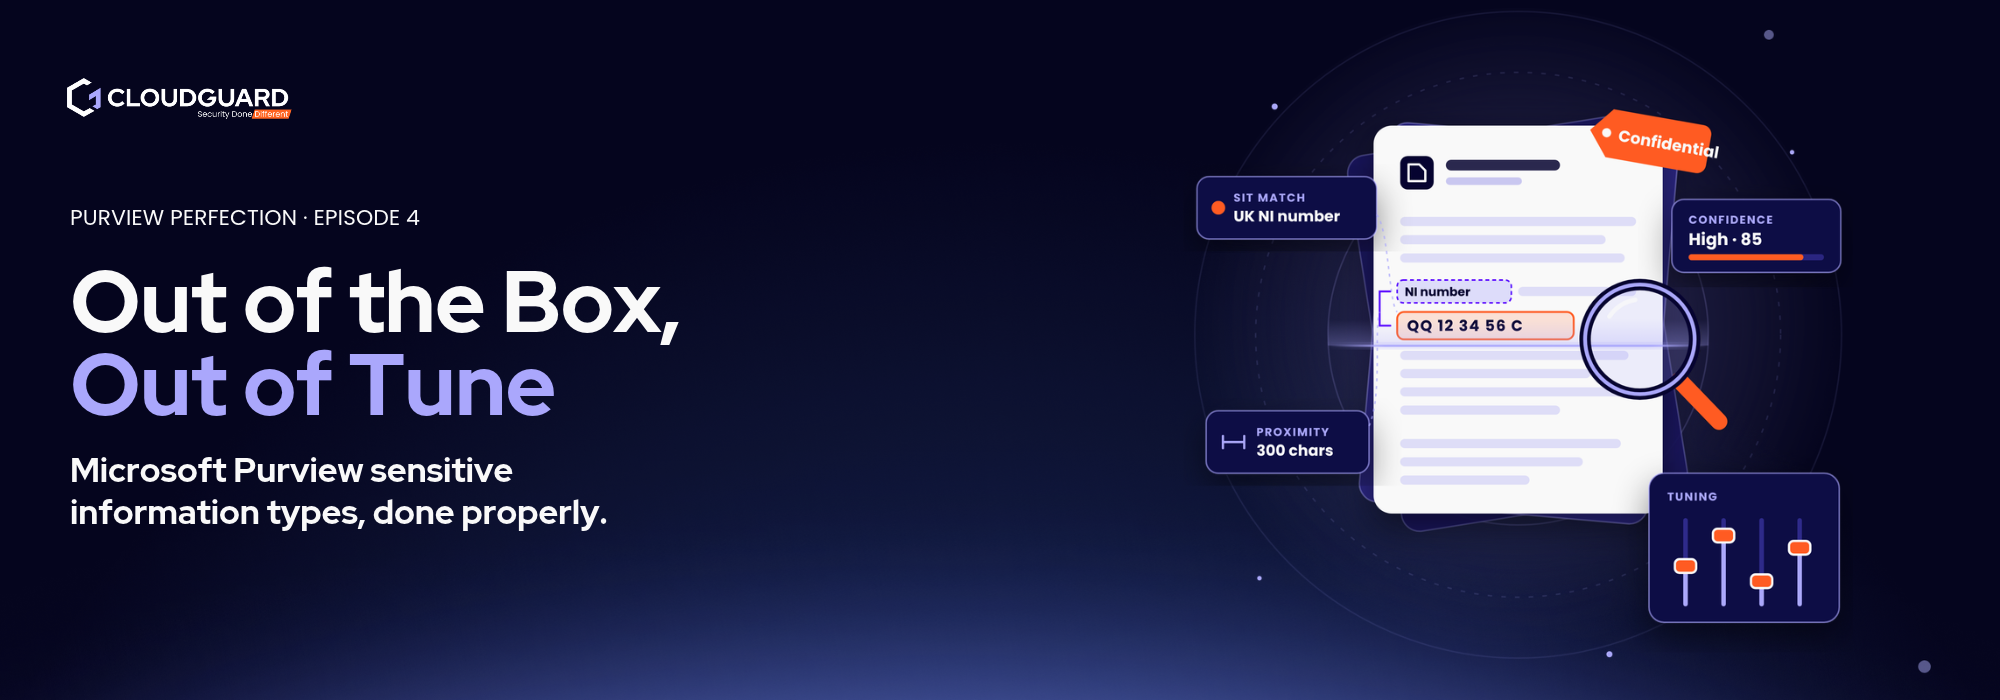
If Purview flagged a document as containing a National Insurance number tomorrow, would you trust it?
Most SMB IT managers assume Microsoft’s built-in detection has it covered. Purview comes with hundreds of ready-made sensitive information types and pre-trained classifiers, so it feels like the hard part’s already done.
But those built-ins were written for everyone, which means they weren’t written for you. Out of the box, they flag things that don’t matter, miss things that do, and quietly feed every auto-labelling and DLP policy you build on top of them.
𝐓𝐡𝐞 𝐂𝐥𝐨𝐮𝐝𝐆𝐮𝐚𝐫𝐝 𝐏𝐎𝐕
You don’t need to throw out Microsoft’s built-in detection. You need to treat it as the starting point, not the finished job.
Your users’ manual labels are the foundation. Tuned sensitive information types and properly trained classifiers are what let Purview take on more of that work accurately, without burying everyone in false alerts.
𝐈𝐧 𝐭𝐡𝐢𝐬 𝐬𝐞𝐬𝐬𝐢𝐨𝐧, our Purview experts break 𝐝𝐨𝐰𝐧:
- Why the built-in sensitive information types and classifiers aren’t enough on their own, with a UK example that shows exactly where they fall short
- How Purview actually decides something is sensitive: patterns, supporting evidence, confidence levels, and how close is “close enough”
- What training and tuning look like in practice, and how to test it all before your DLP and auto-labelling policies depend on it
- Trainable classifiers: what they need to learn, and the decision you can’t take back once you hit publish
- Document fingerprinting and Exact Data Match in plain English, plus the hard limits that catch people out (including how many patterns a single SIT can actually hold)
𝐖𝐡𝐲 𝐬𝐡𝐨𝐮𝐥𝐝 𝐲𝐨𝐮 𝐜𝐚𝐫𝐞?
Get detection wrong and everything built on top of it inherits the problem. You get DLP policies that fire so often your users learn to click “override” without reading. You get auto-labelling that stamps the wrong label on thousands of files. And genuinely sensitive data slips straight past because it didn’t match Microsoft’s idea of what sensitive looks like.
It’s not just labels and DLP anymore either. Purview’s Copilot and AI controls rely on the same detection, so noisy classification means noisy AI governance too.
This isn’t something you switch on and forget. It’s the step lean IT teams rush most often, because nobody’s shown them how to train it properly.
We’re here to give you a straight up & practical walkthrough, from our 𝐏𝐮𝐫𝐯𝐢𝐞𝐰 𝐞𝐱𝐩𝐞𝐫𝐭𝐬 who tune this for SMBs every day.